

Groq is an ultra-fast AI inference platform powered by Language Processing Units (LPU), delivering deterministic, low-latency API execution for open LLMs.
Starting price Freemium / Pay-as-you-go (From $0.05/1M tokens)

Tool Information
Groq platform architecture and Language Processing Unit inference engine
Groq (accessible at groq.com, founded by Jonathan Ross, co-creator of Google’s Tensor Processing Unit / TPU) is the pioneer of real-time artificial intelligence inference hardware, developer cloud infrastructure, and ultra-low-latency execution. Engineered specifically for sequential compute workloads, Groq provides instant response speeds for leading open-source foundation models.
The platform is powered by the custom-designed Groq LPU (Language Processing Unit) Inference Engine, an innovative chip architecture delivering deterministic execution without memory bandwidth bottlenecks. Groq features GroqCloud Developer API (hosting Llama 3.3, DeepSeek, Mixtral, and Gemma), GroqChat (an ultra-fast consumer chat playground), full OpenAI API schema compatibility, and consumption-based pay-as-you-go pricing.
Core hardware capabilities and GroqCloud developer tools
Groq delivers features for low-latency AI inference and real-time streaming applications:
- Ultra-fast token generation speeds: Generates hundreds of tokens per second (often exceeding 500-800 T/s on 8B/70B models) for instantaneous voice and conversational responses.
- Deterministic compute architecture: Delivers predictable inference latency without GPU memory cache stalls or unpredictable latency spikes.
- Comprehensive open-source model catalog: Instant access to Llama 3.3 70B, Llama 3.1 8B, DeepSeek-R1 Distill, Mixtral 8x7B, and Whisper-v3.
- OpenAI SDK drop-in compatibility: Seamlessly integrate into existing applications by updating your base URL and API key.
- Ultra-fast Whisper speech-to-text: Transcribes audio files in fractions of a second using Groq LPU acceleration.
- Enterprise reliability & SLAs: Provisioned capacity and dedicated enterprise clusters for mission-critical production workloads.
Comparative benchmark: Groq vs. Together AI and Cerebras
Groq provides LPU token generation speed, low time-to-first-token, and developer API pricing.
| Dimension | Groq (LPU) | Together AI (GPU) | Cerebras (CS-3) |
|---|---|---|---|
| Hardware architecture | Custom LPU (Language Processing Unit) | NVIDIA H100/B200 GPU clusters | Wafer-Scale Engine (WSE-3) |
| Token generation speed | Fast (approx. 500-800+ tokens/sec) | Standard fast GPU streaming (~100-180 T/s) | Ultra-fast wafer streaming |
| Use case sweet spot | Real-time voice agents, search, instant chatbots | Batch inference, LoRA fine-tuning, image models | High-speed enterprise inference |
| Pricing model | Pay-as-you-go (From $0.05/1M tokens) | Pay-as-you-go (From $0.17/1M tokens) | Pay-as-you-go / Enterprise |
Practical applications and operational limits
- Real-time conversational voice agents: Power voice bots where sub-second latency is critical for natural human dialogue.
- Interactive coding companions: Provide instant code completions and multi-file refactoring without waiting for tokens to stream.
- Live search & summary synthesis: Synthesize live web search results in fractions of a second for end users.
- High-speed audio transcription: Transcribe hours of recorded audio in seconds using LPU-accelerated Whisper models.
Operating limits: Pure pay-as-you-go pricing without monthly base subscription fees. A free developer tier is provided with rate limits (RPM/TPM); production scaling operates on standard token consumption rates.
Pricing structure and token rates
GroqCloud operates on consumption-based per-token pricing with no platform membership fees:
| Hosted Model | Input Rate (per 1M tokens) | Output Rate (per 1M tokens) | Inference Speed & Capabilities |
|---|---|---|---|
| Llama 3.1 8B Instant | $0.05 / 1M tokens | $0.08 / 1M tokens | ~800+ tokens/sec, ultra-low latency, ideal for real-time agentic routing |
| Llama 3.3 70B Versatile | $0.59 / 1M tokens | $0.79 / 1M tokens | ~300+ tokens/sec, strong reasoning, coding, and complex dialogue comprehension |
| DeepSeek-R1 Distill Llama 70B | $0.75 / 1M tokens | $0.99 / 1M tokens | Reasoning model fine-tune for mathematics, science, and algorithmic logic |
| Whisper Large v3 (Audio) | $0.111 / hour of audio | N/A | Fast transcription speed, multilingual automatic speech recognition |
*Pricing and plan details verified as of August 2026.
Step-by-step workflow
- Obtain API key: Register at console.groq.com and generate a developer API key.
- Select model: Choose a model like
llama-3.3-70b-versatileorllama-3.1-8b-instant. - Implement SDK: Point your OpenAI SDK client to
base_url="https://api.groq.com/openai/v1". - Stream responses: Stream ultra-low latency token responses directly into your application.
Editorial verdict
- Best for: AI engineers, software developers, and product teams building real-time voice agents, instant chatbots, and latency-sensitive conversational applications.
- Not recommended for: Non-technical business users looking for a no-code graphical document editor.
- Learning curve: Minimal for developers. 100% OpenAI API compatible.
- Value threshold: Exceptional value. Token rates from $0.05/1M tokens provide cost efficiency and speed.
- Bottom line: Groq is a high-speed AI inference platform, setting industry benchmarks for token generation latency with its custom LPU hardware.
F.A.Q
Pros and Cons
Pros
- Proprietary Language Processing Unit (LPU) hardware delivering fast token generation speeds (500-800+ T/s)
- Competitive pay-as-you-go pricing starting from $0.05 per 1 million tokens for Llama 3.1 8B
- Full OpenAI API schema compatibility enabling 1-line integration with existing codebases
- Fast Whisper speech-to-text transcribing hours of audio files in fractions of a second
- Generous free developer tier available for evaluation, testing, and prototyping
Cons
- LPU architecture is optimized primarily for sequential inference rather than training new base models
- Focuses strictly on developer APIs and chat playgrounds rather than full graphical design applications
- High-volume enterprise applications require monitoring rate limits during global traffic surges
Reviews
There are no reviews yet. Be the first one to write one.
The FASTEST AI Chatbot, Groq (what is it & how to use it)
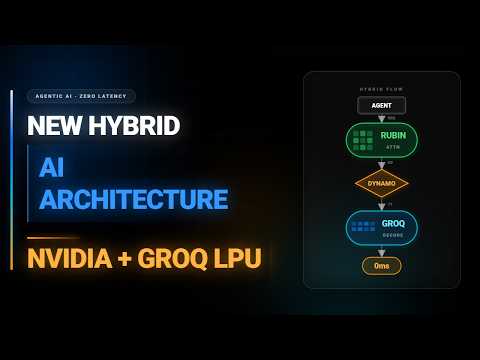
NVIDIA + Groq LPU: 0ms Latency Kills GPU Inference
Author

Promote

Alternative tools

Make is a visual no-code workflow automation platform connecting 1,500+ apps with interactive drag-and-drop scenarios, webhooks, and multi-step AI agents.
2026-08-22
Freemium / $10.59-$34.12/mo

Liner is an AI academic research assistant featuring Liner Scholar with 460M+ academic records, deep research workflows, and verified scholarly citations.
2026-08-22
Freemium / $14.99-$17.99/mo

Julius AI is an AI data analyst platform that executes Python code to clean spreadsheets, build predictive models, and render publication-ready visual charts.
2026-08-22
Freemium / $20.00-$45.00/mo

Google DeepMind is Google's premier AI research lab responsible for scientific breakthroughs and foundational frontier models like Gemini, AlphaFold, and Veo.
2026-08-22
Free

MindsDB is an open-source AI database platform that allows developers to train, fine-tune, and deploy AI models directly inside databases using standard SQL.
2026-08-22
Free (Open Source) / From $49.00/mo Cloud

Rows AI is a next-generation spreadsheet and AI data analyst that extracts tables from PDFs, automates live data integrations, and answers analytical queries in plain English.
2026-09-05
Free / $8/mo